
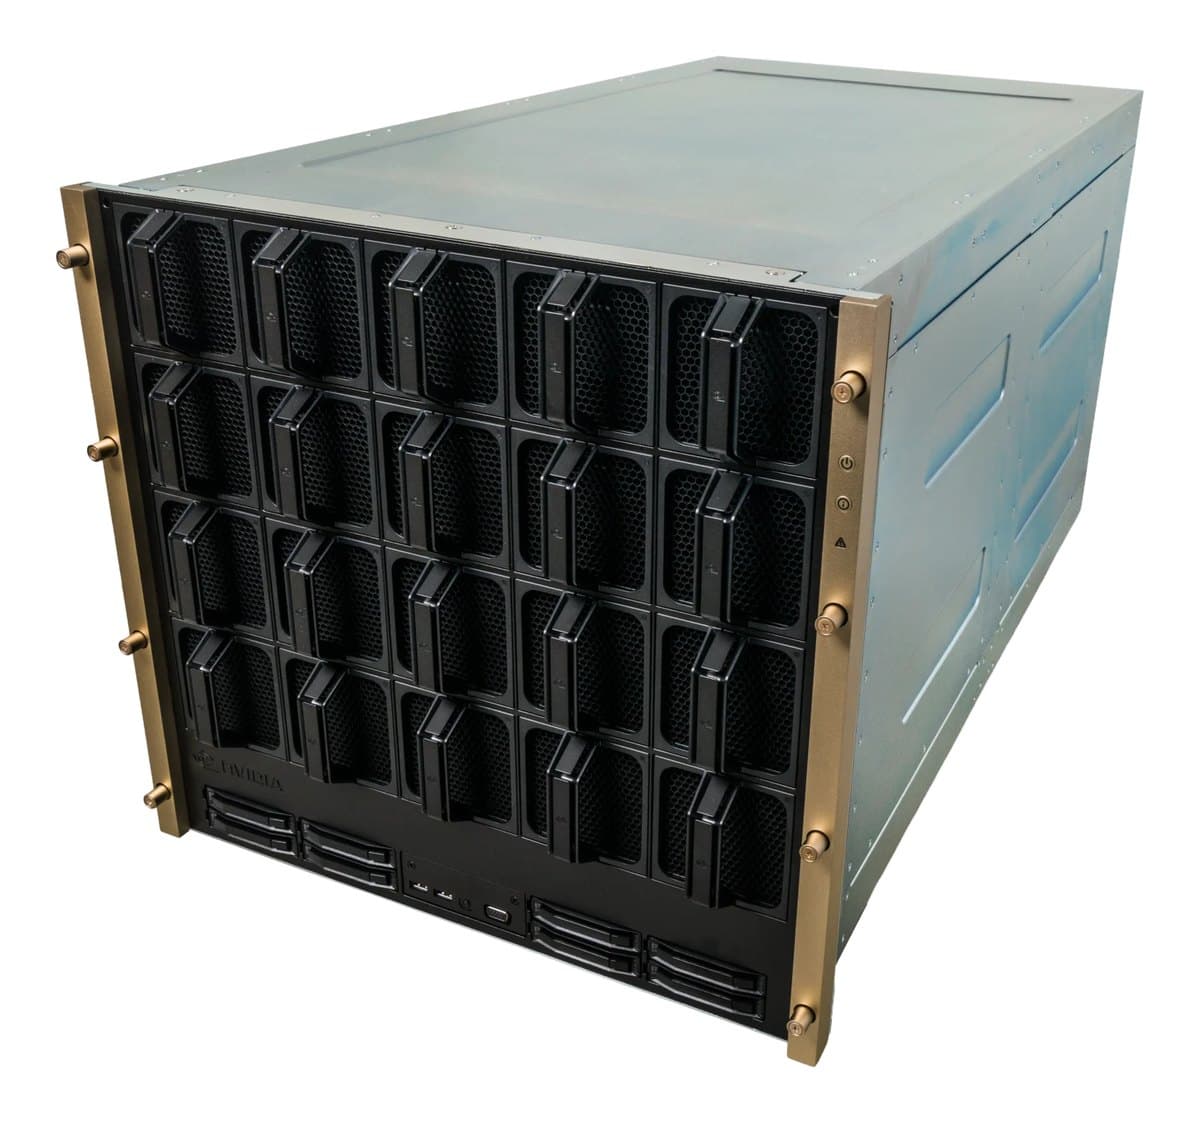
B200 GPU Server
Next-generation Blackwell compute for organizations planning their next AI build-out.
We help you choose, configure, and deliver the right system. No obligation.
Configuration at a Glance
Tailored per engagement. Full technical overview below.
Configuration Options
Core specifications for this system. Every component is configurable to your workload, so request a quote for a tailored build.
NVIDIA B200 (Blackwell)
Dual AMD EPYC or Intel Xeon
Multi-terabyte ECC
Overview
The B200 GPU Server is built on NVIDIA's Blackwell architecture, the latest generation of data-center AI acceleration. Nexus Compute works with organizations planning forward-looking infrastructure to specify, source, and stage delivery of Blackwell-based systems as availability allows. Blackwell changes the planning problem more than it changes the workflow. Per-GPU memory and interconnect are larger, which pushes further out the model size at which work must be split across nodes; the facility requirements move in the opposite direction, because power per node rises and the density that follows makes direct-to-chip liquid cooling the expected answer rather than an option. A building that comfortably hosts air-cooled previous-generation nodes may need coolant distribution, a secondary loop, and leak detection before it can accept a Blackwell rack. Supply is allocation-based, and the sensible stance is a staged one: confirm the facility work first, because it usually carries the longer lead time of the two.
Who This Solution Is For
Business Benefits
Latest-generation performance
Blackwell delivers a significant step up in training and inference performance over the prior generation.
Future-proof investment
Specifying the newest architecture extends the useful life of a major capital investment.
Roadmap-aligned planning
We help align procurement timing with your project roadmap and Blackwell availability.
Staged delivery support
For forward-looking builds, we coordinate sourcing and staged delivery as supply allows.
Typical Business Use Cases
Next-generation foundation model training
Maximum-performance large-model inference
Multi-year AI infrastructure build-outs
Frontier research requiring the latest acceleration
Deployments where facility works run in parallel with procurement
Multi-year build-outs standardizing on current-generation accelerators
Industry Applications
Technical Overview
Built on NVIDIA Blackwell B200 GPUs with next-generation NVLink interconnect, dual server CPUs, very large ECC memory, and high-speed InfiniBand networking. Configurations and availability are confirmed at quote time. Two planning decisions dominate a Blackwell build and both are made before any hardware ships. The first is thermal: whether the node is air- or liquid-cooled determines rack density, and therefore rack count, floor area, and the facility work the deployment implies. The second is fabric: at this class of accelerator the interconnect is usually what limits a multi-node training run, so port count, topology, and optics are specified with the compute rather than after it, under /products/networking. Storage follows the same principle: a faster accelerator is easier to starve, so the NVMe tier is sized both to keep the input pipeline ahead of the GPUs and to absorb checkpoints without stalling the run, with the tiering options under /products/storage. Host CPU and system memory are scaled to the accelerators on the usual ratios.
| GPU | NVIDIA B200 (Blackwell) |
| GPU Capacity | Up to 8 GPUs per node |
| GPU Interconnect | Next-generation NVLink / NVSwitch |
| CPU | Dual AMD EPYC or Intel Xeon |
| System Memory | Multi-terabyte ECC |
| Networking | InfiniBand NDR / 400GbE+ |
| Power | High-capacity redundant PSUs |
| Availability | Confirmed at quote (allocation-based) |
| HBM3e Memory per GPU | 180GB |
| NVLink Generation | Fifth-generation NVIDIA NVLink |
| NVLink Aggregate Bandwidth (8-GPU HGX B200) | 14.4 TB/s |
| FP4 Tensor Performance (8-GPU) | 144 PFLOPS sparse / 72 PFLOPS dense |
Specifications are indicative and configured to each engagement. Request a quote for a configuration tailored to your requirements.
Warranty, Support & Fulfillment
Every system ships from an authorized channel, configured and tested, with the documentation enterprise buyers need: genuine product, backed by the full manufacturer warranty.
Enterprise Warranty
Full manufacturer warranty with optional on-site, next-business-day support and extended coverage.
Authorized Channel
Sourced through Tier-1 distribution and OEM partners (never grey market). Asset & warranty records included.
Lead Time & Deployment
48-hour quotes, then configured, burn-in tested, and delivered on a committed schedule.
Nationwide Fulfillment
Coordinated logistics, rack-and-stack, and delivery wherever your infrastructure lives.
Frequently Asked Questions
Is the B200 available now?
Blackwell supply is allocation-based and evolving. We provide a realistic availability and delivery timeline as part of your quote based on current conditions.
Should I wait for B200 or buy H100/H200 now?
It depends on your project timeline and budget. We help you weigh time-to-deployment against generational performance so the decision fits your roadmap.
What facility planning is needed?
Blackwell systems are high-density and high-power, often favoring liquid cooling. We advise on facility requirements early in planning.
What should we do first if we decide on Blackwell?
Establish what your facility can supply and remove per rack, and start any electrical or cooling work early. Facility lead times frequently exceed hardware lead times, and a node that arrives before the room can power it sits in a crate. We put the facility requirements in writing at quote so your building team or colocation provider can price the work in parallel with procurement.
How does it scale to more nodes?
The same way as any cluster, but the fabric matters more. Higher per-node throughput means the interconnect becomes the limiter sooner, so multi-node Blackwell builds are generally specified with one RDMA-capable port per GPU on a non-blocking topology from the outset. We size switching, cabling, and optics for the final node count, so expansion is a matter of adding nodes rather than rebuilding the network.
What warranty and support comes with it?
Systems are sourced through authorized channels and carry the full manufacturer warranty, with optional on-site and next-business-day cover. At this capital value the support tier is worth deciding deliberately rather than by default, so we set out the options, response commitments, and what each one covers as part of the quote.
Hardware Assistance
Configure the B200 GPU Server with Nexus Compute
Tell us your requirements and a hardware specialist will help you specify, configure, and quote the right system, typically within two business days. No obligation.