
Private AI Infrastructure
A complete, owned AI platform: designed, sourced, and delivered as one engagement.
We help you choose, configure, and deliver the right system. No obligation.
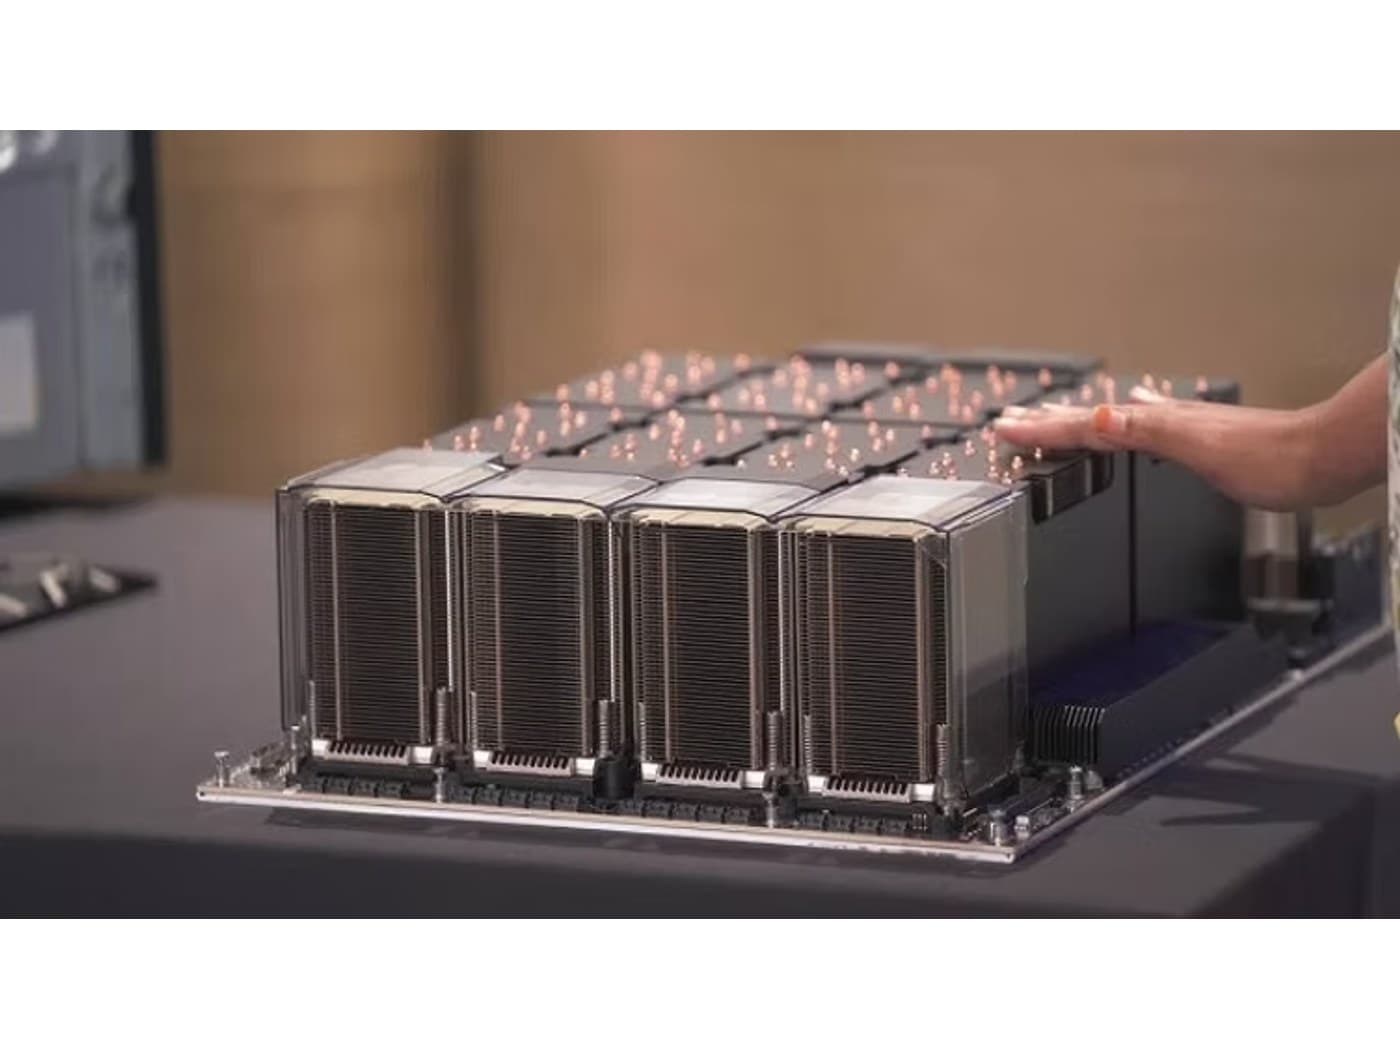
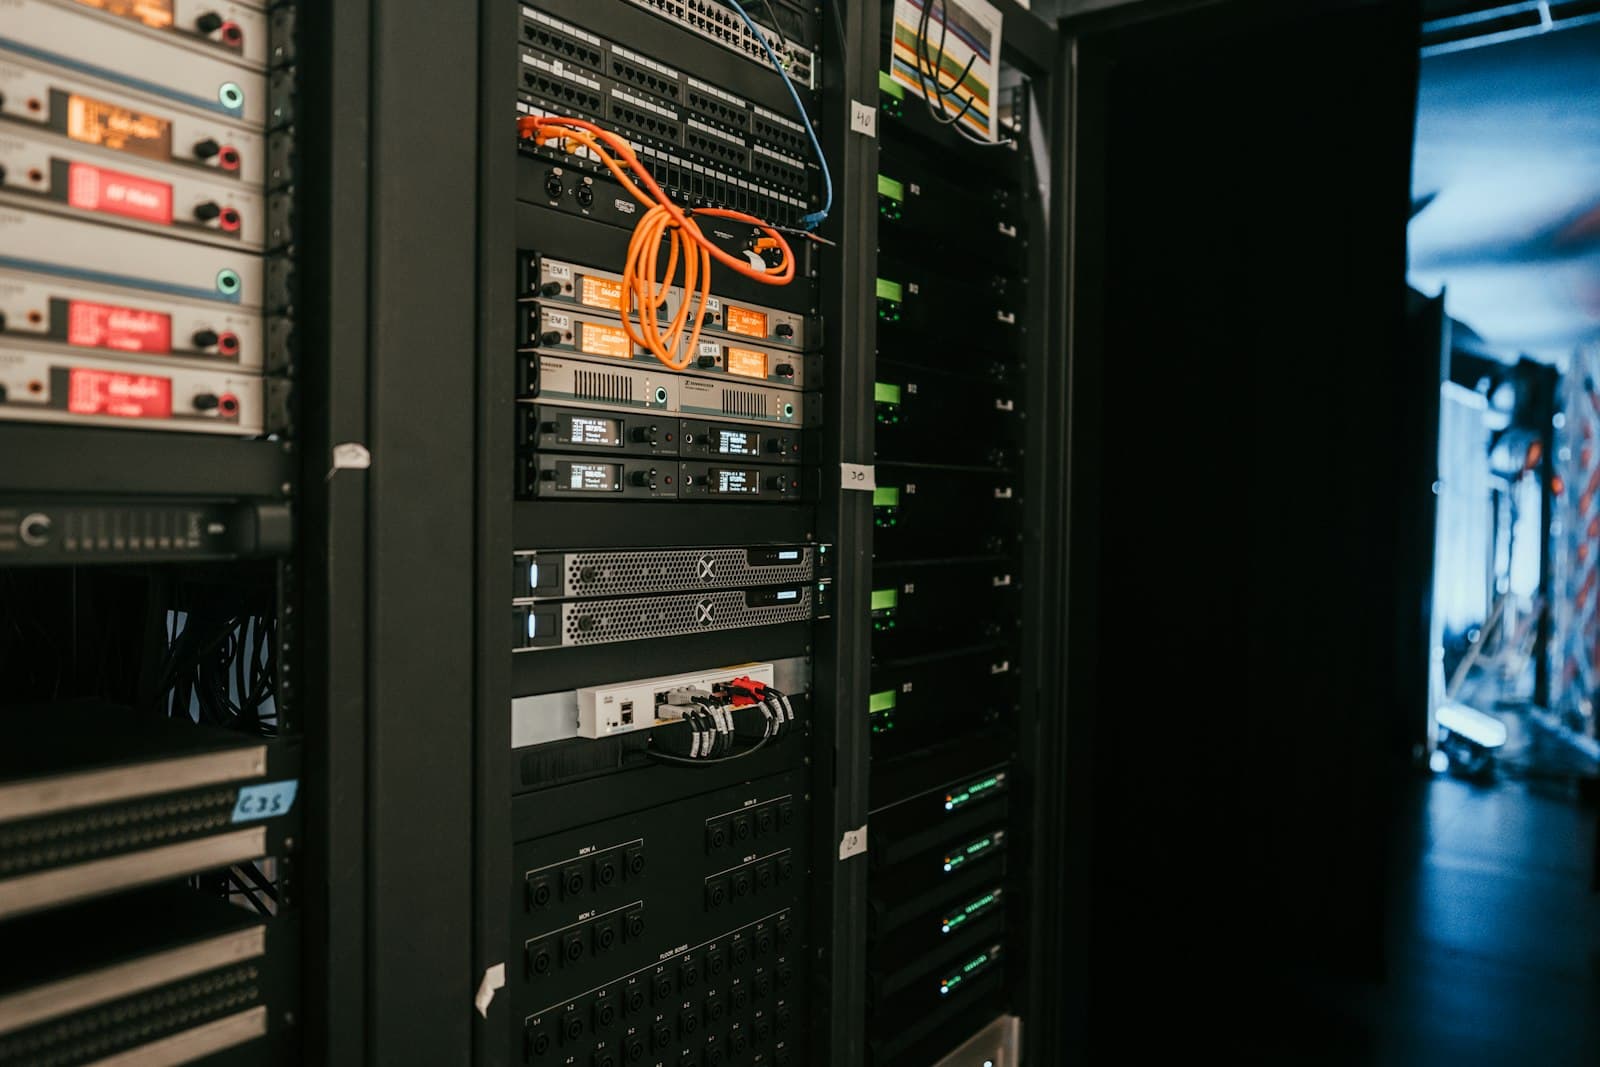
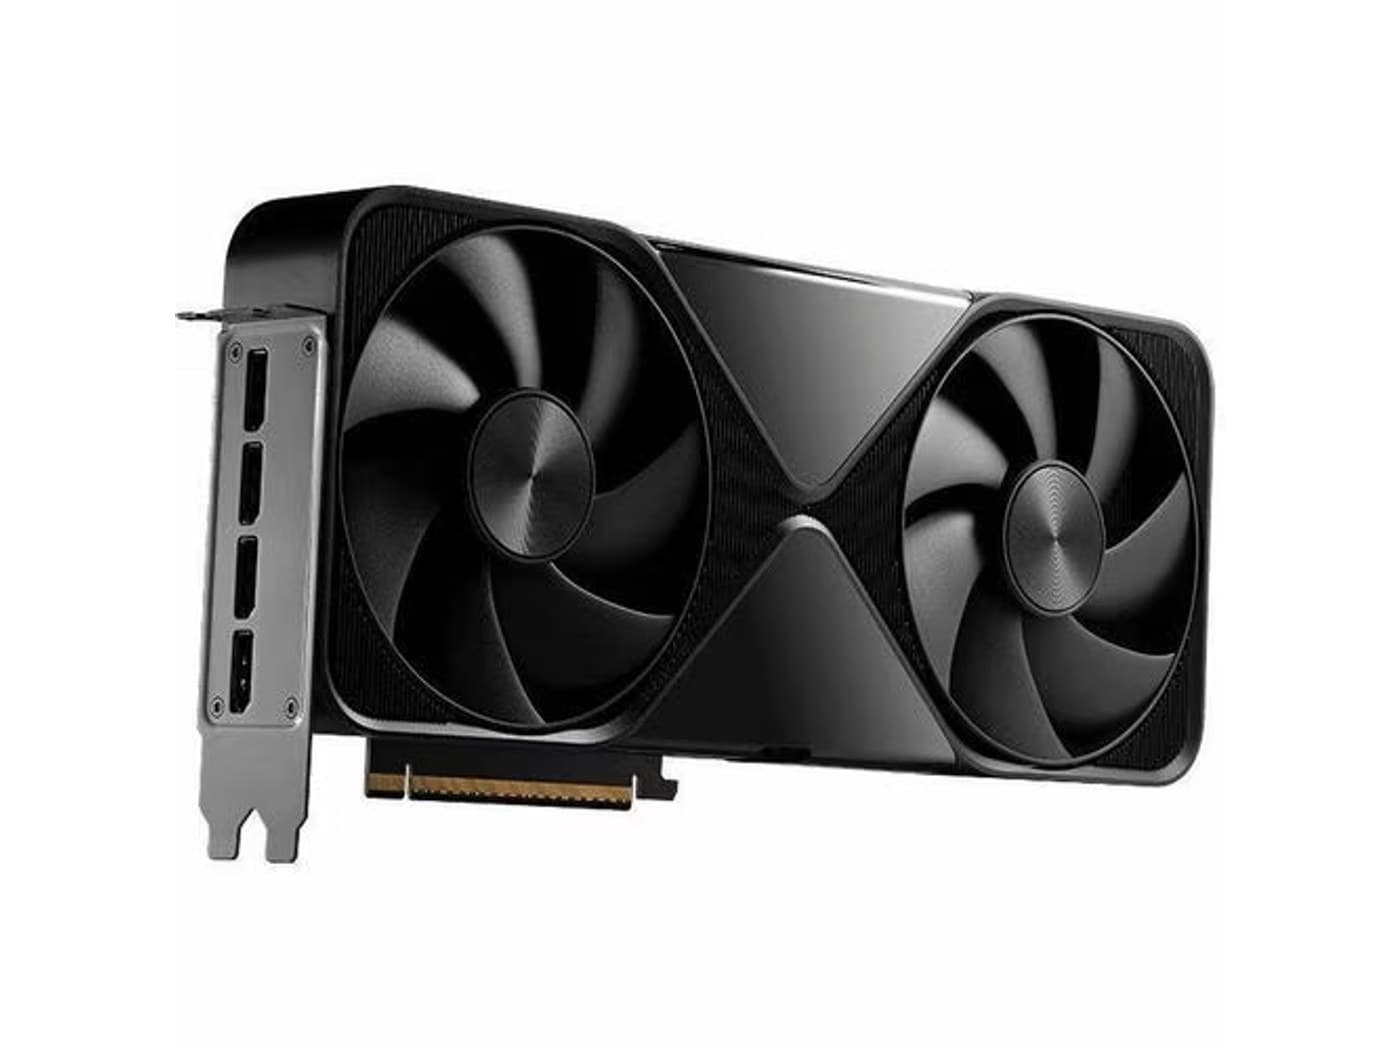
Configuration at a Glance
Tailored per engagement. Full technical overview below.
Configuration Options
Core specifications for this system. Every component is configurable to your workload, so request a quote for a tailored build.
Tiered NVMe + bulk + backup
Overview
Private AI Infrastructure is our end-to-end solution for organizations that want a complete on-premises AI capability they fully own and control. Nexus Compute serves as your infrastructure supplier across compute, networking, storage, and facility planning, turning a complex multi-vendor build into a single, coordinated engagement. An owned platform is three procurement problems that have to agree with one another: the compute, the fabric and storage that keep it fed, and the building that powers and cools it. They carry different lead times (facility work is frequently the longest and is usually started last), so sequencing matters as much as specification. The design also has to accommodate both halves of the workload: training is bursty, synchronous, and fabric-sensitive, while serving is continuous, latency-bound, and needs redundancy. Those want different hardware balances, and a platform intended to do both should be explicit about how capacity is divided rather than assuming one configuration serves both well.
Who This Solution Is For
Business Benefits
Complete ownership and control
Your models, data, and compute remain entirely within your environment: no third-party cloud dependency.
Data sovereignty by design
On-premises infrastructure satisfies residency and sovereignty requirements that cloud cannot always meet.
One coordinated engagement
We integrate compute, networking, storage, and facility planning so you manage one partner, not many vendors.
Predictable long-run economics
For sustained AI workloads, owned infrastructure replaces open-ended cloud spend with a planned investment.
Typical Business Use Cases
Fully private, owned AI platform for an enterprise
Sovereign AI infrastructure for government and regulated bodies
Consolidating distributed cloud AI spend on-premises
End-to-end AI capability with full data control
Running training and production serving on one owned platform
Phased build-outs where facility works run alongside procurement
Industry Applications
Technical Overview
A bespoke, end-to-end design spanning GPU compute (training and/or inference), high-speed networking, tiered storage, and facility/power/cooling planning, integrated with orchestration and monitoring. Every element is specified to your requirements as a single engagement. A private platform is specified in a fixed order, because each layer constrains the next. Facility first: per-rack power, cooling capacity and type, floor loading, and whether liquid cooling is possible, which sets maximum density and therefore rack count. Then compute, split between training and serving with their differing requirements acknowledged. Then the fabric, sized for the eventual scale rather than the first phase, since re-cabling a live rack is disruptive: the options are under /products/networking. Then storage as tiers: NVMe close to the GPUs for scratch and checkpoints, a shared parallel tier for datasets, and bulk plus backup behind that, each sized against how many nodes read at once, as covered under /products/storage. Orchestration, identity, monitoring, and backup are specified with the hardware, because a platform without them is a set of servers.
| Compute | Training and/or inference GPU clusters (configurable) |
| Networking | InfiniBand and/or high-speed Ethernet fabric |
| Storage | Tiered NVMe + bulk + backup |
| Orchestration | Kubernetes / Slurm + monitoring |
| Facility Planning | Power, cooling, and rack planning advisory |
| Engagement | End-to-end design, sourcing, and delivery |
| Scale | Sized to organizational requirements |
Specifications are indicative and configured to each engagement. Request a quote for a configuration tailored to your requirements.
Warranty, Support & Fulfillment
Every system ships from an authorized channel, configured and tested, with the documentation enterprise buyers need: genuine product, backed by the full manufacturer warranty.
Enterprise Warranty
Full manufacturer warranty with optional on-site, next-business-day support and extended coverage.
Authorized Channel
Sourced through Tier-1 distribution and OEM partners (never grey market). Asset & warranty records included.
Lead Time & Deployment
48-hour quotes, then configured, burn-in tested, and delivered on a committed schedule.
Nationwide Fulfillment
Coordinated logistics, rack-and-stack, and delivery wherever your infrastructure lives.
Frequently Asked Questions
What does an end-to-end engagement include?
We work with you from requirements through design, multi-vendor sourcing, staged delivery, and commissioning advisory, coordinating compute, networking, storage, and facility planning as one project.
Can you work within our existing data center?
Yes. We design around your existing facility constraints, or advise on colocation if on-premises capacity is insufficient.
How do we start?
Begin with a consultation. We assess your AI objectives, data requirements, and facility, then propose a phased infrastructure plan and quote.
What should we have ready for a useful first conversation?
Five things turn a generic answer into a specific one: the workloads you intend to run and the largest model among them, the throughput or user numbers you must support, your node-count expectation over two to three years, what your facility can supply and cool per rack, and the deadline. Without the facility figure in particular, any specification remains provisional.
How do we compare this with continuing on cloud?
By utilization, honestly measured. We will not put a payback figure in a quote that we cannot substantiate. The comparison worth making is your actual consumption (not your peak and not your forecast), priced at your current rates, against purchase, power at your tariff, facility cost, support, and the staff time to run it. Sustained high-duty-cycle workloads generally favor ownership, intermittent ones generally do not, and a mixed estate is a legitimate answer.
What lead times should we plan around?
Current-generation accelerators are allocation-based, networking and storage are usually shorter, and facility work is frequently the longest of the three. We build the schedule around whichever is the binding constraint for your project, and identify what can be delivered and commissioned early so the whole program does not wait on a single line item.
Hardware Assistance
Configure the Private AI Infrastructure with Nexus Compute
Tell us your requirements and a hardware specialist will help you specify, configure, and quote the right system, typically within two business days. No obligation.