
Nexus HGX A100 8x SXM4 80GB Training Node
Eight NVSwitch-linked A100 80GB GPUs for full-scale model training.
We help you choose, configure, and deliver the right system. No obligation.
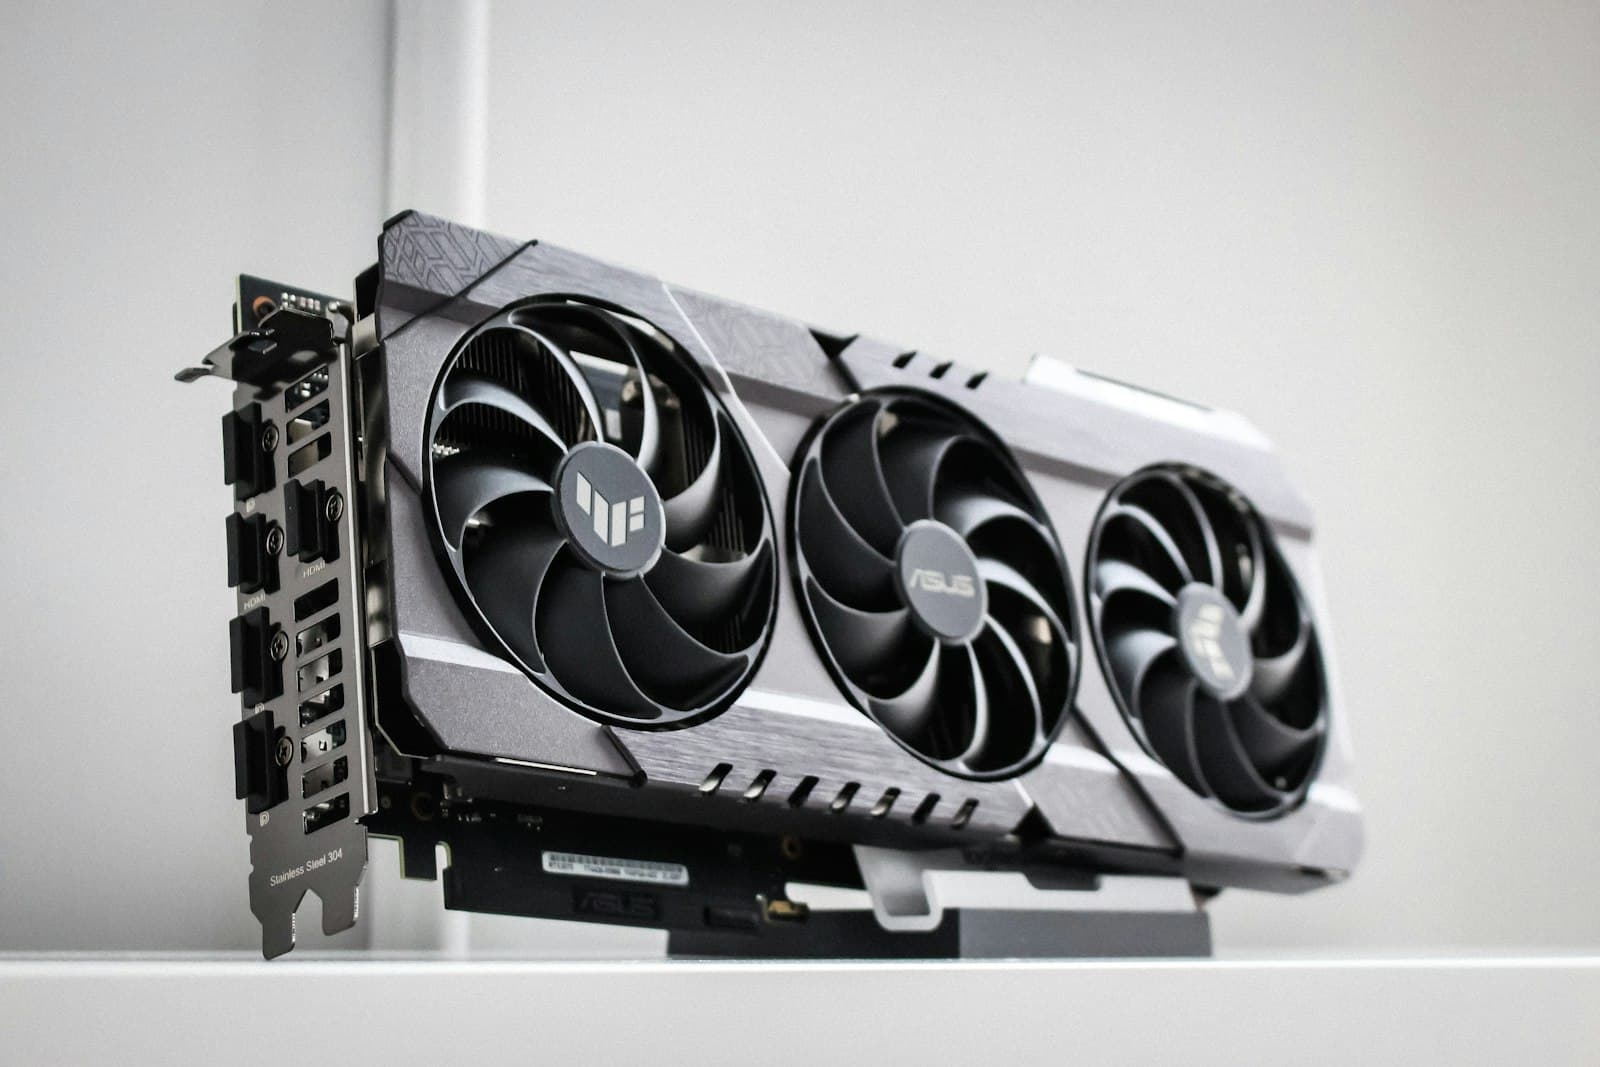
Configuration at a Glance
Tailored per engagement. Full technical overview below.
Configuration Options
Core specifications for this system. Every component is configurable to your workload, so request a quote for a tailored build.
8x NVIDIA A100 SXM4 80GB HBM2e
Dual AMD EPYC 7763 (64-core)
1TB–2TB DDR4-3200 ECC
Hot-swap NVMe (configurable, up to 60TB)
Overview
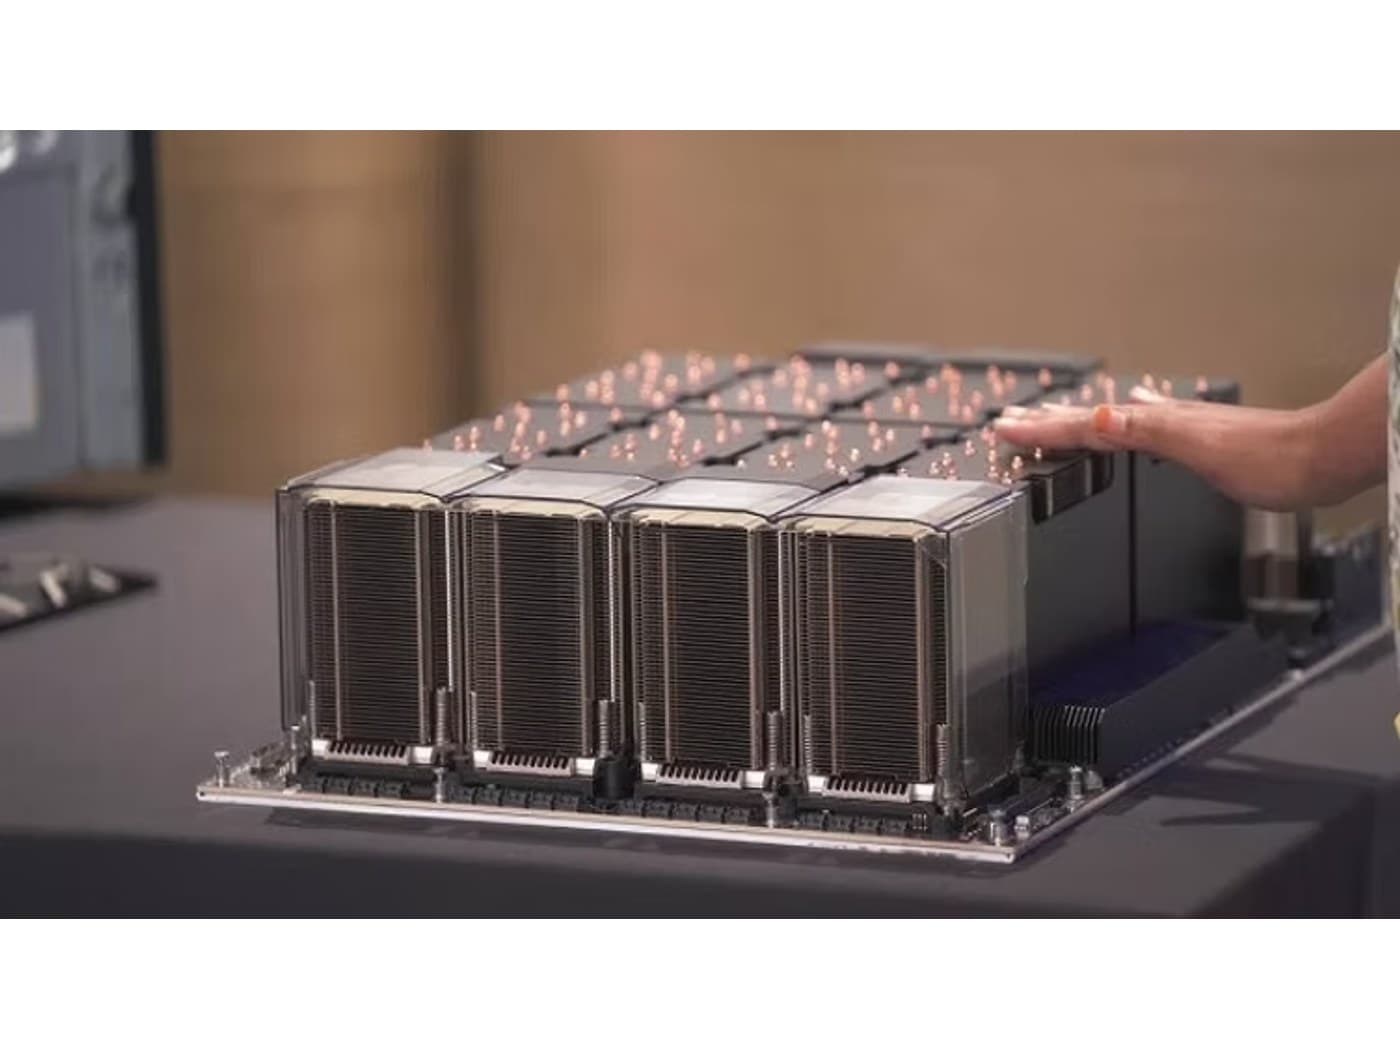
This HGX A100 baseboard couples eight SXM4 A100 80GB GPUs through third-generation NVSwitch for non-blocking all-to-all bandwidth across the node. Nexus Compute specifies, configures, burns-in, and warranty-backs each system through authorized channels for production-grade training and HPC.
Who This Solution Is For
Business Benefits
Full all-to-all bandwidth
NVSwitch links all eight GPUs at 600 GB/s so large models shard efficiently within one node.
Burned-in and validated
Every node is stress-tested across GPUs, fabric, and thermals before it ships.
Proven training platform
The HGX A100 reference design carries mature CUDA, NCCL, and framework support.
Typical Business Use Cases
Large language model pre-training and fine-tuning
Distributed training with NCCL all-reduce
Mixed-precision HPC simulation
Multi-team shared training capacity
Industry Applications
Technical Overview
Built on the NVIDIA HGX A100 8-GPU SXM4 baseboard with six NVSwitch chips delivering 600 GB/s per-GPU bidirectional NVLink bandwidth. Dual-socket AMD EPYC hosts feed the GPUs via PCIe Gen4 with InfiniBand HDR for cluster scaling.
| GPU / Accelerator | 8x NVIDIA A100 SXM4 80GB HBM2e |
| GPU Interconnect | Third-gen NVLink via 6x NVSwitch (600 GB/s/GPU) |
| CPU | Dual AMD EPYC 7763 (64-core) |
| Memory | 1TB–2TB DDR4-3200 ECC |
| Storage | Hot-swap NVMe (configurable, up to 60TB) |
| Networking / Fabric | InfiniBand HDR 200Gb + dual 25GbE |
| Form Factor | 4U rackmount |
| Power | 4–6x redundant 3000W PSUs |
| Warranty | 3-year warranty with advanced parts replacement |
Specifications are indicative and configured to each engagement. Request a quote for a configuration tailored to your requirements.
Warranty, Support & Fulfillment
Every system ships from an authorized channel, configured and tested, with the documentation enterprise buyers need: genuine product, backed by the full manufacturer warranty.
Enterprise Warranty
Full manufacturer warranty with optional on-site, next-business-day support and extended coverage.
Authorized Channel
Sourced through Tier-1 distribution and OEM partners (never grey market). Asset & warranty records included.
Lead Time & Deployment
48-hour quotes, then configured, burn-in tested, and delivered on a committed schedule.
Nationwide Fulfillment
Coordinated logistics, rack-and-stack, and delivery wherever your infrastructure lives.
Frequently Asked Questions
How many GPUs can a single HGX A100 node hold?
This configuration is a fixed 8-GPU SXM4 baseboard; all eight A100 80GB GPUs are interconnected by NVSwitch as one tightly-coupled unit.
Is this suited to training or inference?
It is optimized for multi-GPU training and HPC where NVLink all-to-all bandwidth matters; for partitioned serving consider our PCIe MIG configurations.
Can it scale beyond one node?
Yes. The integrated InfiniBand HDR adapters let multiple nodes form a non-blocking training fabric, which we size during specification.
Hardware Assistance
Configure the Nexus HGX A100 8x SXM4 80GB Training Node with Nexus Compute
Tell us your requirements and a hardware specialist will help you specify, configure, and quote the right system, typically within two business days. No obligation.